Topics / LLM Internals
LLM Internals
2 talks
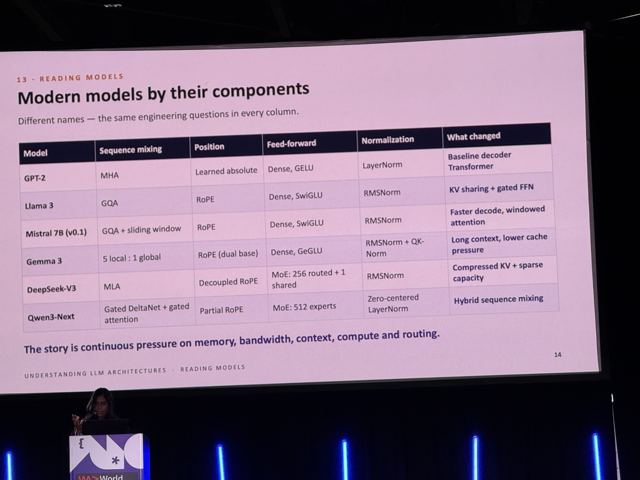
Understanding LLM Architectures: Inside the Design of Modern Models
Jofia Jose Prakash · Humanity + AI · 30 min
Đọc LLM hiện đại theo component (GQA, MLA, local attention, MoE, Gated DeltaNet) và biết phải đo gì khi swap model trong production.
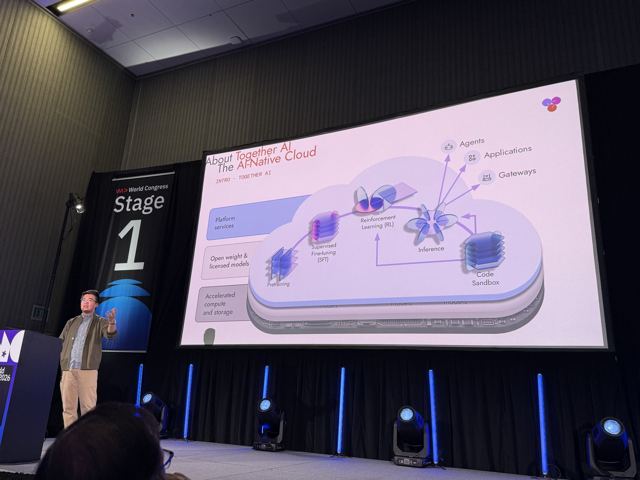
Anatomy of an AI Request: Where Latency and Cost Are Really Born
Dan Fu · Together AI · 35 min
Sáu stage một AI request đi qua (routing tới decode) và sáu lever giảm latency, cost: kernels, disaggregation, parallelism, routing, speculative decoding, quantization.